
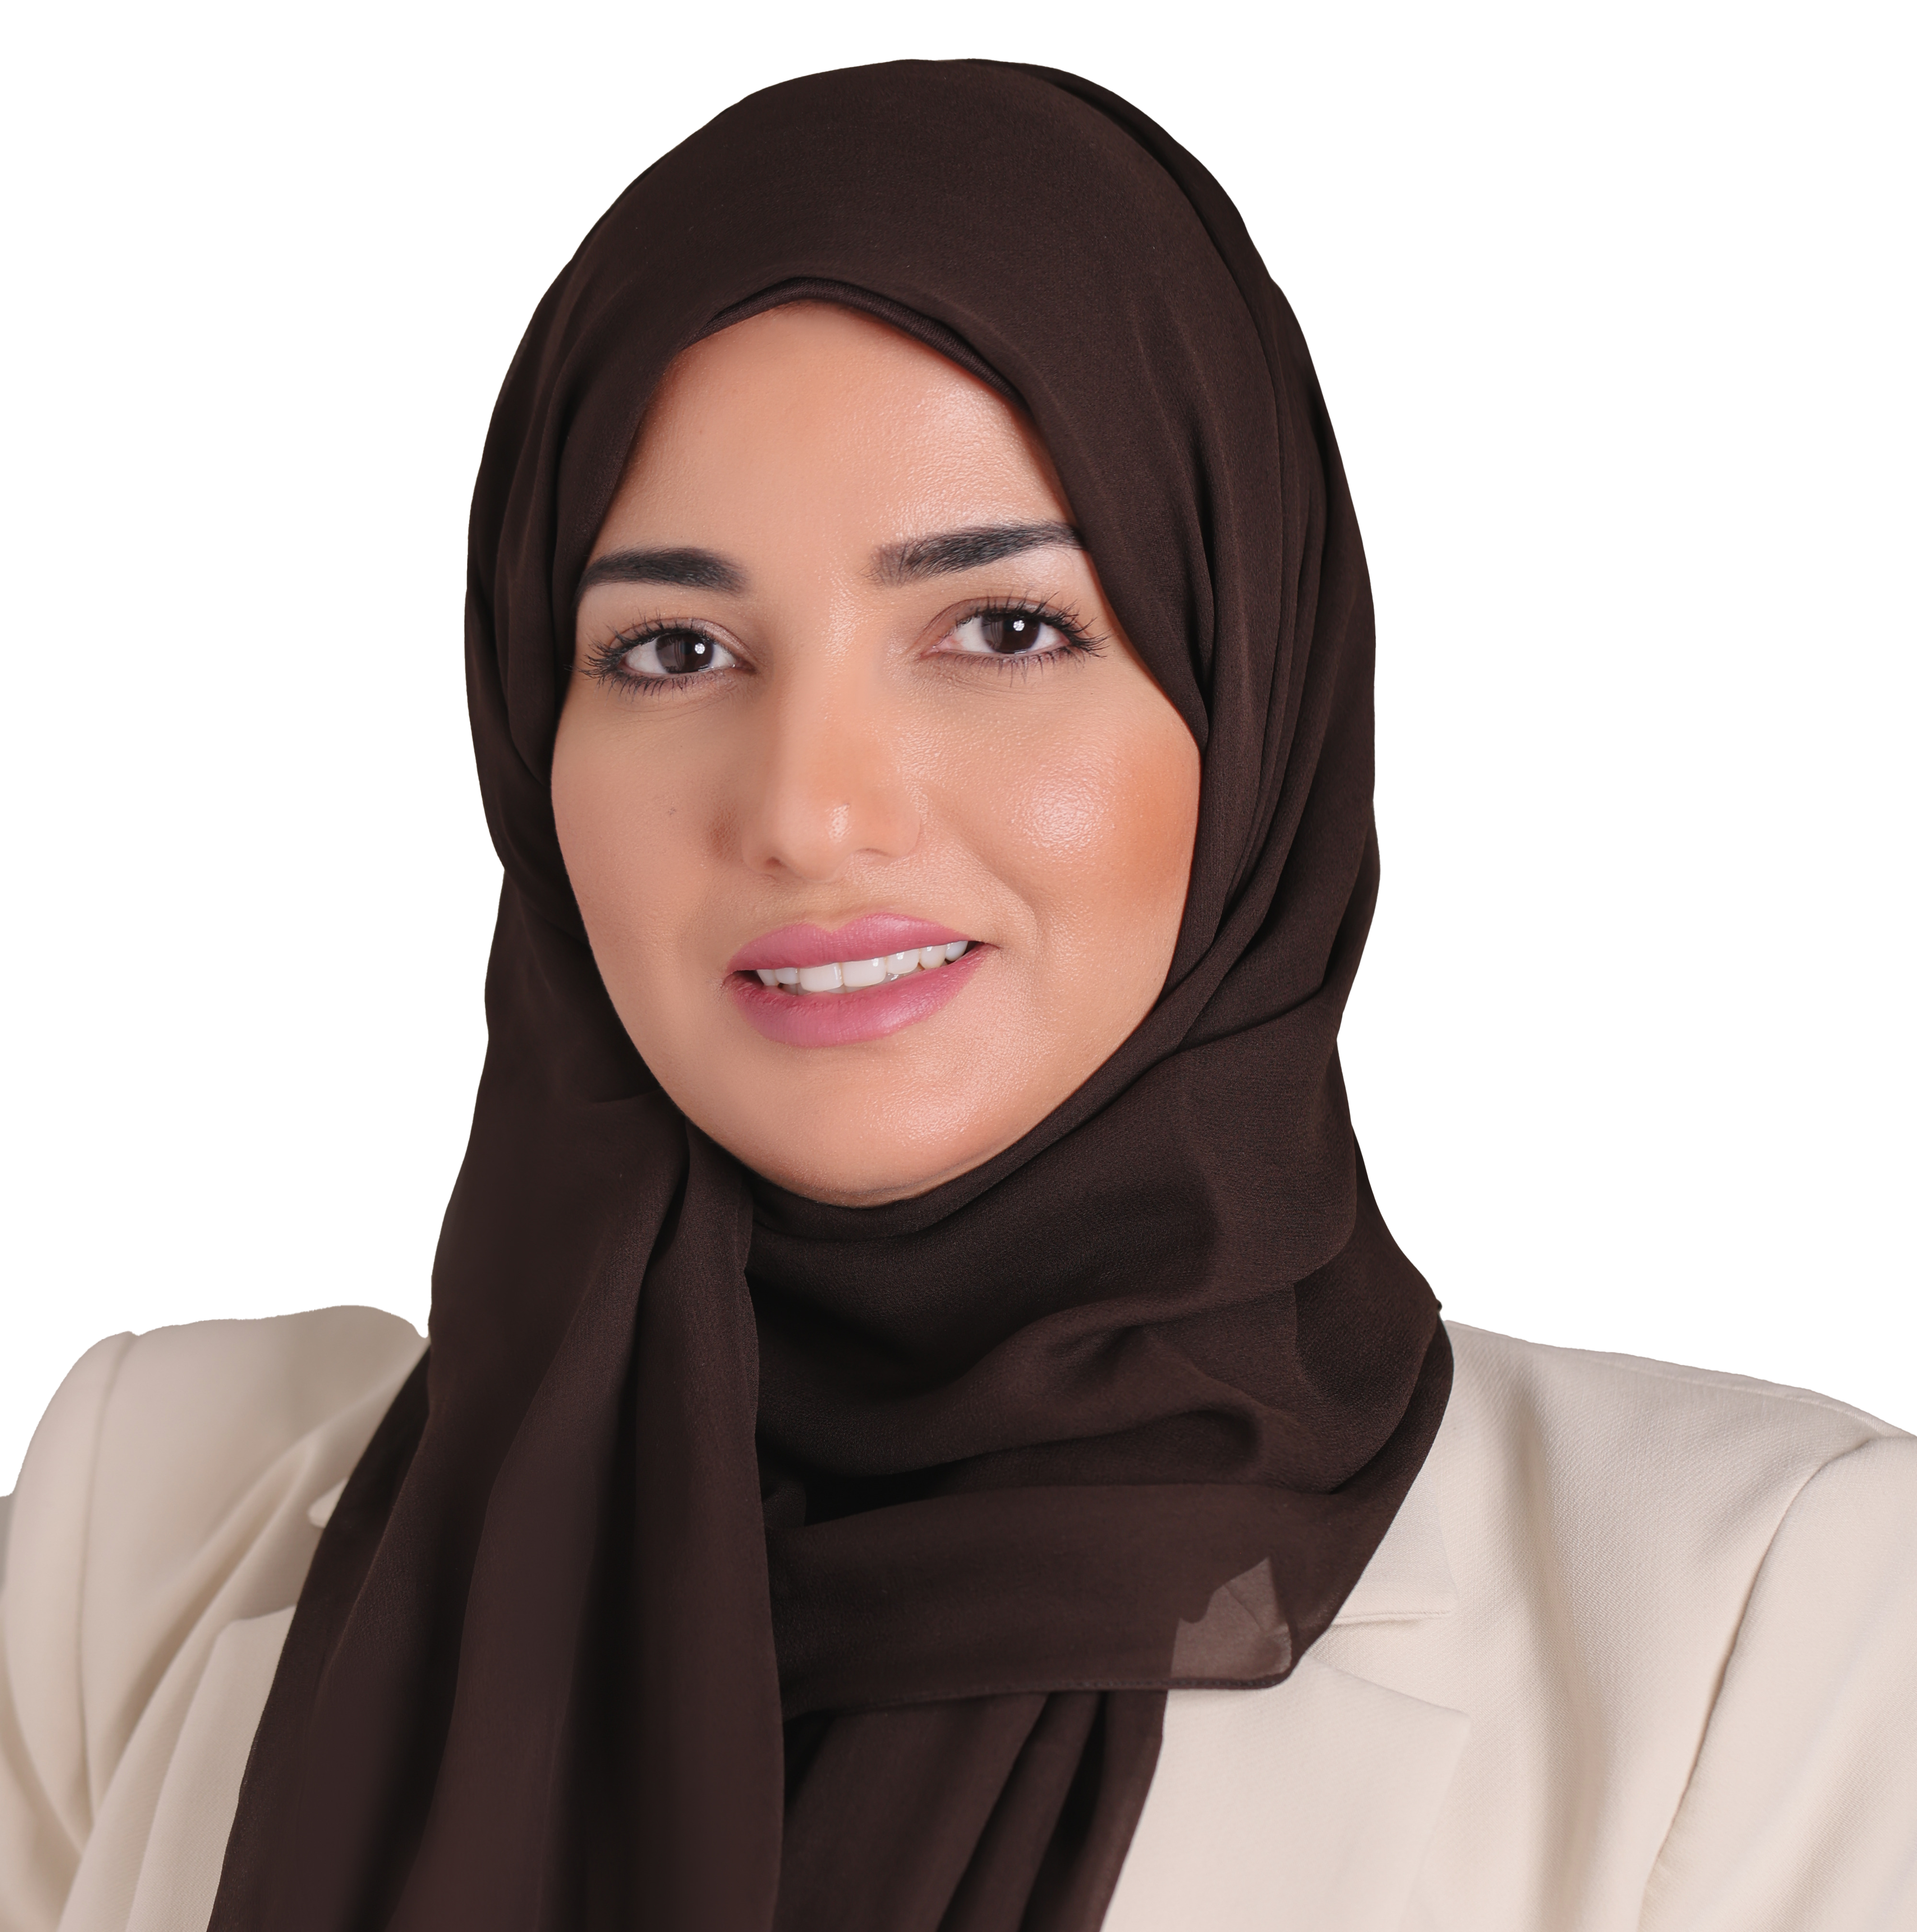
Fatemah Alharbi
Associate Professor
Taibah University
Prof. Fatemah Alharbi is a leading cybersecurity researcher, consultant, and public speaker, serving as Global Ambassador for Saudi Arabia at the Global Council for Responsible AI (GCRAI). She is an Associate Professor at Taibah University, Yanbu, and a member of its Advisory Board, while advising several startups. She has received prestigious awards, including the Top Cybersecurity Woman of the World and Top International 40 Under 40. Recognized among the most prominent Arab female scientists, her work focuses on cybersecurity, AI, resilience, and ethical innovation. She actively leads impactful initiatives advancing research, education, and women’s empowerment aligned with Saudi Vision 2030.
Speaker sessions
Briefings and Arsenals | Confirmed Speakers | No Session Assigned
Placeholder session for confirmed speakers without an assigned session, allowing them to be pushed to Swapcard and Visit.
- 07:30
- Tue
- 01 Dec
Stage:
Briefing Stage 2
Sessions Type:
Keynote
Red Teaming Arabic LLMs: Measuring Safety Failures at Scale
As Arabic Large Language Models (LLMs) are increasingly deployed in sensitive and high-impact domains, their resilience against adversarial misuse remains largely untested. Unlike English models, Arabic LLMs lack dedicated safety benchmarks, creating blind spots that attackers can exploit.In this session, we present SalamahBench, a large-scale red-teaming framework designed to systematically probe safety failures in Arabic LLMs. The benchmark consists of over 8,000 adversarial prompts spanning 12 harm categories aligned with the MLCommons Safety Hazard Taxonomy. These prompts were generated using a hybrid pipeline combining automated methods with multi-stage human validation to simulate realistic attack scenarios.We evaluate five state-of-the-art Arabic LLMs�Fanar 1 & 2, ALLaM 2, Falcon H1R, and Jais 2�under multiple safeguard configurations. Our findings reveal measurable and often inconsistent safety weaknesses across models, with some systems demonstrating strong resistance overall but failing under specific categories of harm. Others show consistently higher susceptibility to prompt-based attacks.This talk highlights how attackers can exploit these gaps and demonstrates the need for category-aware defenses and standardized safety evaluation in non-English AI systems. Attendees will gain practical insights into red-teaming methodologies, emerging risks in Arabic AI, and strategies to improve robustness against adversarial misuse.
- 13:20
- Tue
- 01 Dec
Stage:
Briefing Stage 2
Sessions Type:
Keynote